In this article
Back-End Development in 2026: Architecture Choices That Determine Scale
Tech & Infrastructure
The difference between a system that absorbs growth and one that collapses under its first serious traffic spike is almost always decided at the architecture level, not in the code. In 2026 the stakes are higher than ever: traffic has become more volatile, AI workloads consume resources unpredictably, and a single mention of your product […]
The difference between a system that absorbs growth and one that collapses under its first serious traffic spike is almost always decided at the architecture level, not in the code. In 2026 the stakes are higher than ever: traffic has become more volatile, AI workloads consume resources unpredictably, and a single mention of your product in a popular app can send hundreds of thousands of users your way within hours. That is why architecture choices in back-end development are no longer a technical footnote but a strategic decision that determines how far a business can scale before everything has to be rewritten.
What Actually Determines the Scalability of Your Backend
Plenty gets written about scaling, but most advice targets systems that will never face real load. As a result, teams pour energy into fashionable patterns and then trip over the basics: the database, session state, and slow external calls. A scalable backend architecture is, above all, an honest separation of decisions — the ones that genuinely define your ceiling, and the ones that merely look modern.
The idea worth internalizing before any technology is this: almost every wall that growth runs into is a wall of data and state. Application servers scale horizontally by adding nodes behind a load balancer. A single database, shared session state, or a synchronous call to a slow AI service does not multiply so easily. So what follows is not about the “right” framework but about the architecture choices that set your scaling ceiling long before the first line of business logic is written.
The Database Is the Architecture Choice That Sets Your Scaling Ceiling
If one decision determines scalability more than any other, it is the data model. It gets chosen at the start and is painful to change later, often with downtime and migrations on a live product. The sharding key, whether your access patterns are compatible with read replicas, the absence of heavy cross-shard joins on hot paths — all of it is baked into the schema while traffic is still low, and it later either leaves room to grow or turns into your primary bottleneck.
The practical default in 2026 remains “boring” and reliable: a relational database such as PostgreSQL, with distributed options (Vitess, CockroachDB, or managed cloud variants) reserved for when a single primary genuinely runs out of room. Reaching for Cassandra or a zoo of five specialized stores in week one means buying operational complexity against load that does not yet exist. It is far smarter to design the schema so the seams for future sharding already exist, even while the database is still a single instance.
To stop the database from becoming a scaling limiter, several things deserve attention at the design stage:
- Partitioning key — the field along which data naturally divides (user, tenant, region) without constant cross-queries.
- Read and write patterns — whether heavy reads can move to replicas without breaking consistency.
- Indexes for real queries, not “just in case,” since redundant indexes slow down writes.
- An archival strategy for old data, so hot tables do not grow without bound.
Monolith or Microservices: When to Complicate the Architecture
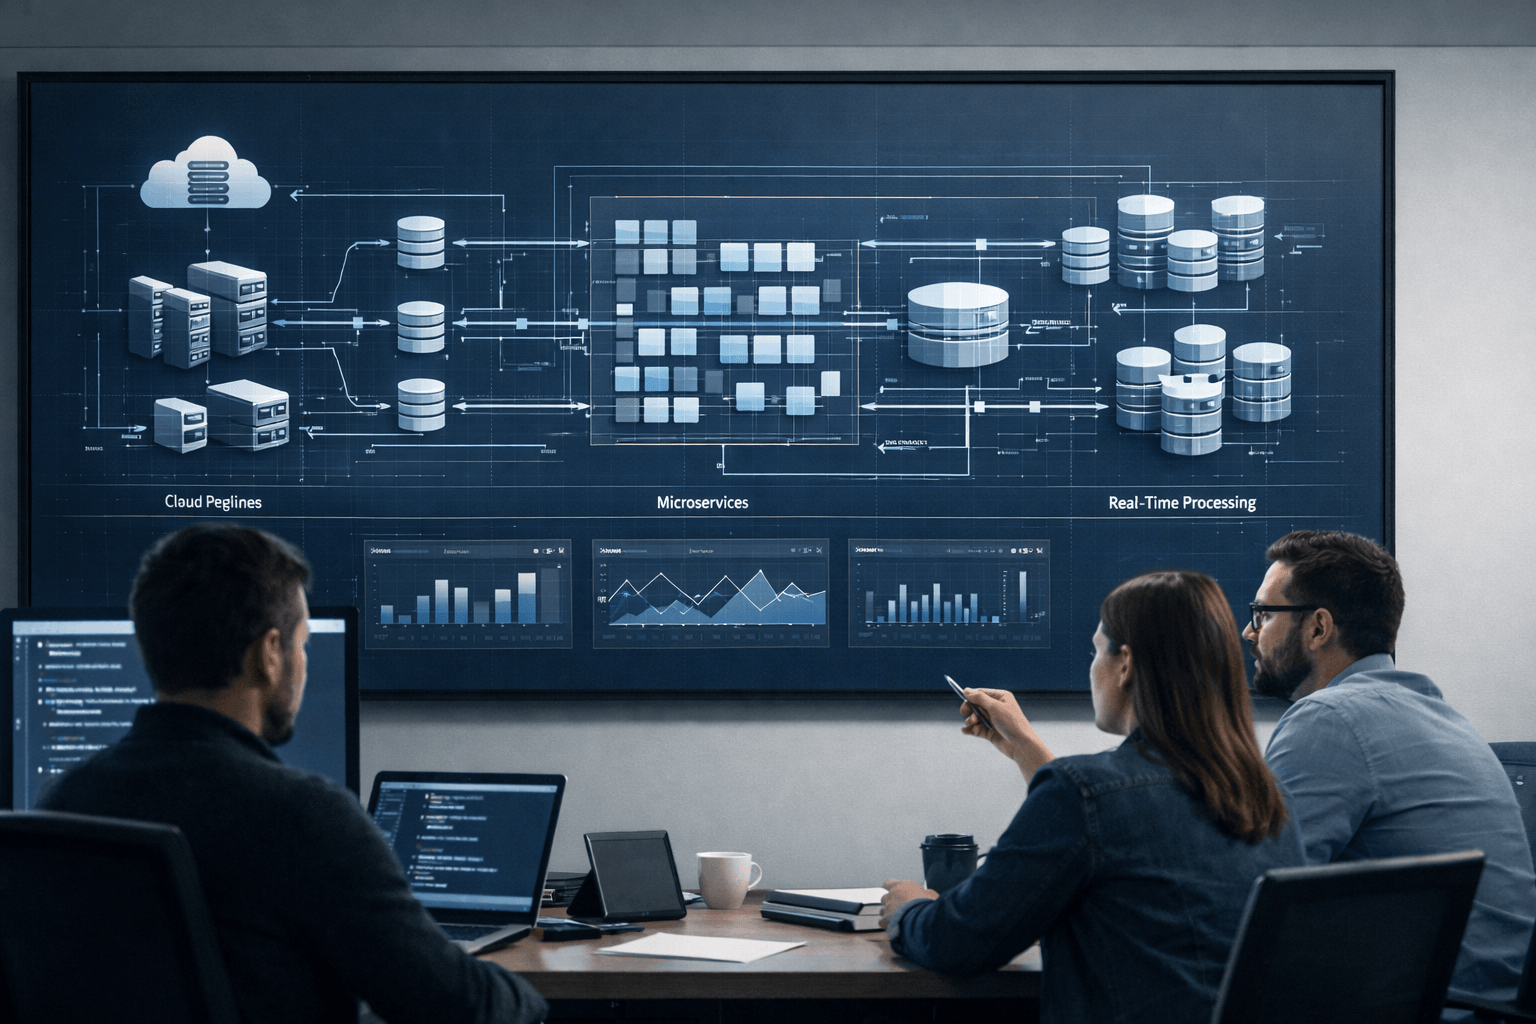
The choice between a monolith and microservices is usually framed as technical, when it is really a question of team organization. The industry has genuinely matured toward microservices in 2026, and the tooling around them has improved — but the classic mistake has not changed: teams adopt a distributed system before they have the traffic or the people to operate it. The result is trading a performance problem they do not yet have for a debugging problem they cannot handle.
A well-built modular monolith scales remarkably far — on vertical hardware, read replicas, and a queue for background work. It lets a small team move fast, because a function call stays a function call and a transaction stays a plain BEGIN … COMMIT. Microservices earn their place when a specific component has a fundamentally different scaling profile (heavy media processing or AI inference, for example), or when team size turns a shared codebase into a constant source of merge conflicts and blocking.
A familiar example is a startup that splits a product into twenty services with ten engineers, then discovers that simple changes now require a coordinated deploy of several components, and investigating a single bug becomes a tour through the logs of five applications. Splitting for its own sake gives you network calls where you used to have in-memory calls, and distributed transactions where a single database once sufficed. So the architecture choice here is this: split the system along the seams of real load and team boundaries, not along the lines of fashion.
Asynchronous Work and Queues: How a Backend Survives Traffic Peaks
The most powerful scaling pattern is barely marketed, because you cannot buy it as a product: moving slow work out of the request–response cycle. The moment anything expensive — sending emails, processing images, calling third-party APIs, generating reports, running AI inference — happens through a queue rather than inside the request, the user’s response time stops depending on how long that work takes. Alongside that, retries on failure become possible, and traffic spikes get absorbed as a backlog of jobs instead of a cascade of outages.
This is what people are gesturing at when they talk about event-driven architecture with Kafka, RabbitMQ, or cloud queues. But the principle runs deeper than any specific broker: the hot request path should do the minimum, and everything else is a background job. A typical scenario: a user uploads a video, the backend immediately returns “accepted for processing” and drops a task on the queue, while transcoding happens in separate workers that can be scaled independently of the web servers.
An asynchronous approach gives a backend several properties that are critical for scaling:
- Load decoupling — a burst of requests becomes a longer queue rather than a service failure.
- Fault tolerance — a task can be retried if an external service is temporarily unavailable.
- Independent worker scaling — heavy processing scales separately from the main application.
- Predictable latency — the user does not wait on the slowest operation in the chain.
Serverless or Containers: Choosing for the Shape of Your Workload
The serverless-versus-containers debate is often presented as a “maturity tier,” when it is really a decision about the shape of the workload. Serverless (functions as a service) genuinely wins where traffic is spiky, event-driven, and unpredictable: you pay nothing at idle, and scaling happens automatically. For glue code, event handlers, and background triggers, it is often the optimal choice in terms of both effort and cost.
At the same time, serverless is a poor candidate for latency-sensitive hot paths because of cold starts, for long-running processes, and for steady high throughput, where you effectively overpay for elasticity you do not need. Containers on Kubernetes or a managed equivalent give predictable performance and control wherever the system runs constantly and intensely. That is why most mature architectures in 2026 are hybrid: containers hold the steady core, and serverless handles the bursts at the edges and the events.
The mistake is a religious commitment to one approach for the whole system. A realistic setup looks like this: the main API lives in containers behind an autoscaler, nightly report generation and file-upload reactions run on serverless functions, and a load balancer and a queue connect these parts. The architecture choice here is not “what is trendier” but matching the tool to the real profile of each slice of the workload.
Stateless Architecture and Caching as the Foundation of Scaling
Horizontal scaling works under one condition: application servers hold no state. If a user’s session is “pinned” to a specific node, you cannot freely add and remove servers behind the load balancer. So session state moves to Redis or to the client, and then any request can be served by any node — which is the precondition for cheap scaling out.
The next lever, which often delivers an order-of-magnitude gain before you ever touch the database architecture, is caching. Redis for hot data, a CDN in front of static assets and reads, a cache for the results of heavy computations — all of it takes load off the most expensive resource, the database. A real-world example: a catalog page opened millions of times a day does not need to be rebuilt from scratch every time — a result cached for a few seconds saves the primary database from overload at peak.
These things look mundane, which is why they get underrated, even though they do most of the work in real scalable systems. Stateless servers, a caching layer, and a load balancer provide the headroom that lets many products never reach the point of needing sharding or microservices at all. In other words, a clean stateless architecture with smart caching is the foundation without which any “advanced” scaling solution will perform poorly.
AI Inference in 2026 Back-End Development: A New Constraint on Scale
A defining feature of back-end development in 2026 is that AI inference has become a full-fledged architectural constraint. A model call is expensive, latency-heavy, and often capped by provider rate limits. Put it directly into the request cycle, and every user waits on the slowest link, while a spike in demand runs straight into the external API’s quotas. So inference deserves the same treatment as any slow dependency: move it into asynchronous processing where possible, and cache repeated results aggressively.
A practical example is a chat feature where the model’s response is streamed, while heavier tasks (classification, embeddings, analytics) are pushed onto a queue and handled by a pool of workers. This not only smooths latency but also provides a graceful degradation mechanism: when the AI service is overloaded or unavailable, the system returns a simplified response or queues the task instead of throwing an error at every user at once.
Intelligent scaling also works in the other direction: AI is increasingly used to forecast traffic peaks, automatically expand infrastructure, and optimize cloud costs. But the core architectural conclusion is unchanged: anything slow and unpredictable in cost has no business on the hot path. In back-end development, scalability is increasingly determined by exactly how carefully you have isolated expensive AI calls from the main request flow.
Observability and Security: The Architecture You Do Not See
Observability is the thing without which a scalable system becomes unmanageable. When there are many components and calls are distributed across services, debugging without tracing turns into guesswork. So end-to-end tracing, metrics, and structured logs (built on something like OpenTelemetry) are not a bonus but part of the architecture: without them you scale blind and learn about a problem only once users have already seen it.
Security in 2026 has likewise stopped being a “pre-release” stage and become an architectural discipline. The perimeter model — “build a wall and trust everything inside it” — is incompatible with how modern backends are built, with dozens of integrations and external APIs. It is replaced by a zero-trust approach: every call is authenticated and authorized regardless of where it came from. Retrofitting fine-grained access control into an already distributed system is one of the most miserable tasks there is, which is why this decision is made at the start.
The minimum set that keeps a scalable architecture manageable and secure looks like this:
- End-to-end request tracing across all services for fast problem localization.
- Metrics and alerts on key signals (latency, errors, queue depth), not just “the server is alive.”
- Zero-trust authentication and granular access rights from day one.
- Secrets management through Vault or a cloud secrets manager instead of variables in code.
The Essentials of a Scalable Backend Architecture
Compressed to a single sentence, the scalability of a backend is determined primarily by how you handle state and how you handle slow work. The database sets the ceiling, stateless servers and caching provide the headroom, queues absorb the peaks, and isolating expensive AI calls protects the hot path. The rest of the decisions — programming language, the specific message broker, monolith versus microservices — matter far less than the sheer volume of articles on those topics would suggest.
The main guidance for back-end development in 2026 is not to over-complicate the architecture in advance, but to build in the seams that make the system easy to split when the time comes. Companies that build on simple yet well-designed choices today will scale cheaper and faster than those planning to “rewrite it all someday.” A scalable architecture is not about fashionable technology but about consistent engineering decisions, each of which leaves room to grow rather than taking it away.